 Robofauna
Zero install, zero cloud
All computation runs on your device. Robot files are never sent to a server.
Open a tab and your own CPU or GPU trains a small biped to stand and walk with reinforcement learning (PPO), the simulation side of NanoEmu's sim-to-real pipeline. Watch every policy move in 3D as it learns. No Python setup, no cloud GPU, no robotics degree.
rl.robofauna.com · opens in a new tab

Makers, students and researchers who want a small ESP32-and-servo robot to walk. Most open biped projects train in Python on a dedicated GPU machine. RL Lab needs only a browser.
You built the robot. Now make it walk without setting up a training rig.
See what reinforcement learning actually does, one policy update at a time.
Change rewards and PPO settings, keep training, and compare policies side by side.
Each robot gets its own experiment, and each experiment holds one policy per goal.
Pick a robot from the library. NanoEmu, a 14-joint biped, is ready today.
Stand without falling, recovering from a 5 cm drop or a push. Or walk on command: forward, backward and turning.
Train with MuJoCo physics for reference accuracy, or experimental WebGPU physics that runs thousands of robots at once.
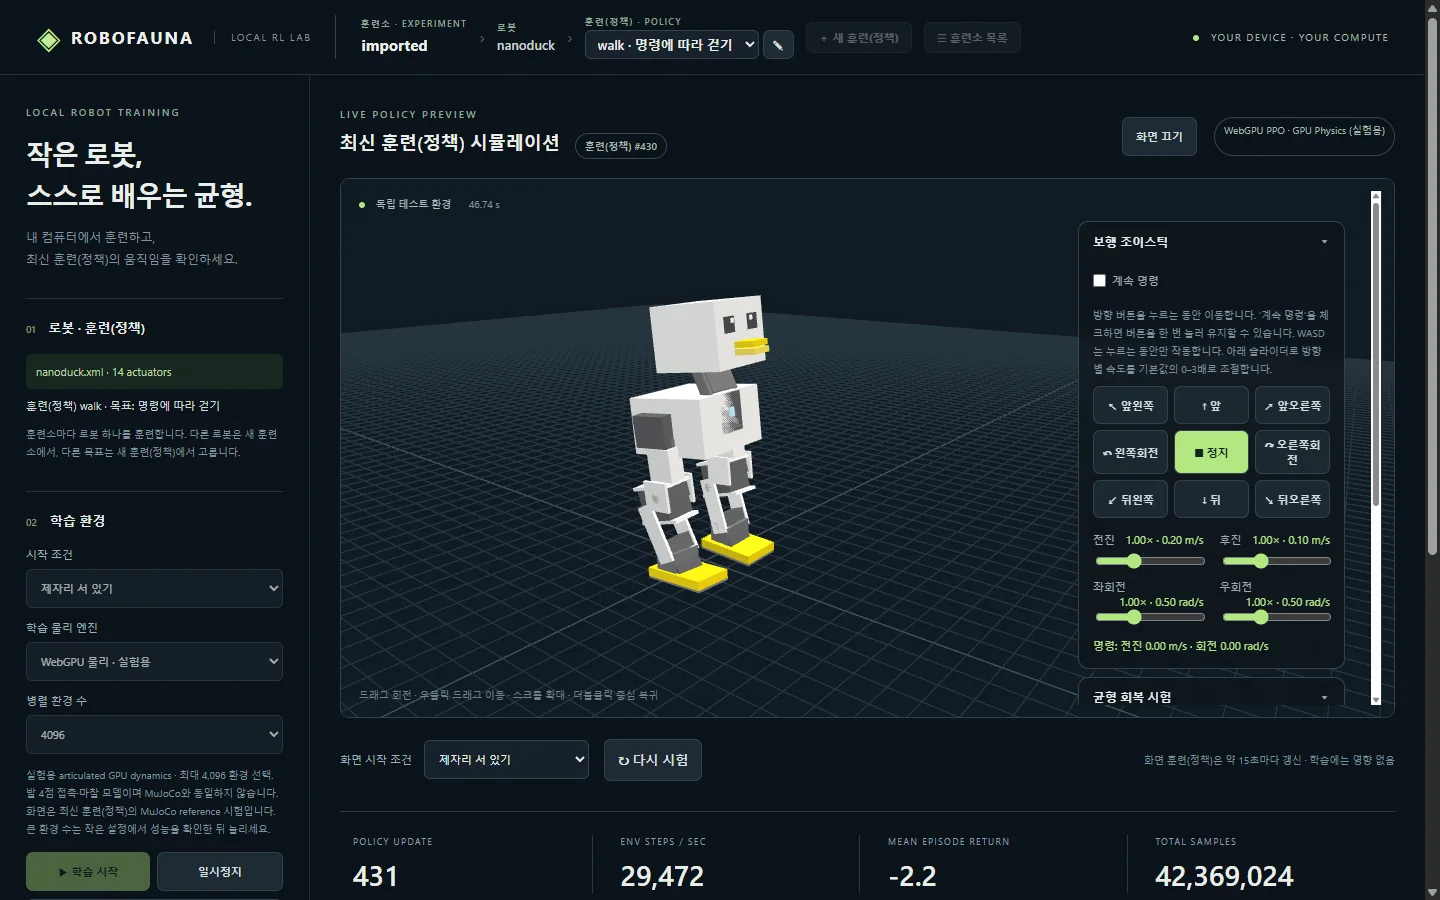
The latest policy drives the robot in 3D. Steer with an 8-way joystick or WASD, push it, drop it, and check the numbers.
Experiments save in the browser automatically. Export them to a file, change settings and keep training.
Captured from the current development build. Names and the robot model will change before launch.



Built with TypeScript, MuJoCo WASM, WebGPU (WGSL), TensorFlow.js, Three.js and IndexedDB.
All computation runs on your device. Robot files are never sent to a server.
MuJoCo is the accurate reference. WebGPU physics is experimental and runs about 17,000–29,000 steps per second.
The newest policy moves the robot while training continues, so you see progress as it happens.
Reward curve, real speed, command error, fall count and a walking check, not just a rising number.
Set zero, direction, min and max angle and the start pose for each joint to match your real servos.
Keep several policies per robot. Everything restores on reload, and exports to a file.
Learning rate and other PPO settings, per-term reward weights and walking command ranges.
Command walking in eight directions, or push and drop the robot to test balance recovery.
Training 4,096 NanoEmu robots at once on a GPU produced a policy that follows forward, backward and turning commands in one to two hours. It passes an independent MuJoCo check. Recovery from pushes is still being improved.
WebGPU physics needs a browser with WebGPU support. MuJoCo training runs on the CPU.
Train in the browser, test in the browser, then run it on the real robot and share it.
Walking works. Sitting down and standing up are next.
Export a policy from the web as an ESP32 file and run it on the real robot.
Import your own robot XML, from a dog to a hexapod or humanoid, and design rewards by hand or by chatting with AI.
Upload robots and policies, download them and keep training someone else's (remix).
Fixed-base reaching and tracking tasks.
RL Lab opens in a new tab. Everything runs on your machine.